How I used an AI agent to recover 18 years of a .NET user group's history
How I used AI agents and archived sources to reconstruct 18 years of Wroc.NET history: 170 meetings, 32 extra events, 185 speakers, and 300 talks.
I run wrocnet.org, the site of the Wrocław .NET user group. The group has been meeting since 2007, but its 18-year history was never kept in one place. I wanted a real archive: every meeting, talk, and speaker in one spot, backed by sources, and built to last. Getting there meant digging through old websites, forum posts, and archived pages, and I used an AI agent to do most of that digging. This post explains how I used the agent to research sources, how I verified its findings, and what the final numbers mean.
My research across archived websites, event pages, social media, email, and project records uncovered:
- 18 years of community history
- 170 meetings and 32 additional events
- 185 speakers
- 300 talks
A history that moved three times
The problem was that the site itself had moved three times over the years, and each move left part of the history behind:
wroc.net.isvclub.com, the very first site, from November 2007 to early 2008wrocnet.orgon Community Server, from 2008 to 2009- a BlogEngine.NET-style blog at
wrocnet.org, from December 2010 to spring 2013 - Meetup, from March 2013 onward, which is still the main source for talk descriptions today
I found no surviving snapshot from late 2009 through most of 2010, so it is unclear what, if anything, the group used during that stretch.
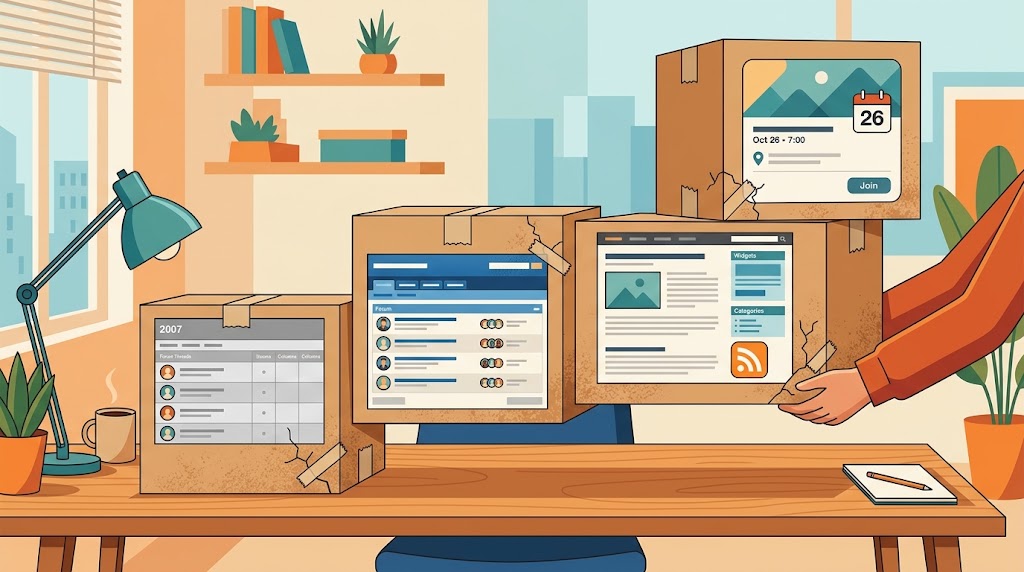 Every platform move carried some of the group’s history forward and left some of it behind.
None of these systems kept a full, clean copy of its own history, and nothing bridges them automatically. I assigned the repetitive work to the agent. It opened Wayback Machine snapshots, compared timestamps for the same URL, downloaded Meetup event pages, and checked one date against three unrelated sources before writing anything into a Jekyll post.
Finding the real size of the gap
The repository already had a basic list of old meetings: numbers, dates, and one-line topics pulled from an archived snapshot of an earlier version of the site, wrocnet.github.io. That snapshot lists meetings like “17 Dec 2019 » 122. spotkanie - Azure Cognitive Services, Azure Sphere, Multi-tenant Azure,” and it gave the repository its numbers, dates, and topics for roughly meetings 48 through 122, long before anyone went looking for speakers, agendas, or sources.
Once I compared file names, front matter numbers, and post content side by side, gaps appeared everywhere. Some meeting numbers had no post at all. Some posts had a date but no number. Some entries were a single sentence with no agenda or speaker. Until then, I had used the AI agent for coding. I now pointed it at the research itself: open a browser, use a terminal, and go through old pages one by one.
What the agent actually did
Across many sessions, the agent:
- pulled archived pages from the Wayback Machine for
wroc.net.isvclub.comand the earlywrocnet.org, including meeting plans, after-event reports, photo galleries, forum threads, and polls - downloaded Meetup event pages with
curland parsed the embedded JSON with a small Node.js script to extract the event title, date, venue, and description reliably, instead of scraping visible HTML - went through an exported HTML copy of the group’s old Twitter/X profile to recover meetings 20 through 32, a stretch that initially looked like a dead period for the group
- read an exported email invitation (pasted directly into the conversation) to recover the “Heroes {Community} Launch” conference from 2008, a source type completely different from a public web page
- checked GoldenLine, old forum threads, and photo gallery indexes whenever the original announcement page had no surviving snapshot
None of these sources tells the whole story on its own. A gallery proves a meeting happened, but it says nothing about what was discussed there. A forum thread shows people were talking about a date; it does not confirm the meeting took place. Most of the work was judging how much to trust each source, instead of combining everything into one confident-sounding answer that might be wrong.
Rules the agent had to follow
The research stayed useful only because we were strict about evidence. A few rules repeated across every session:
- An announcement confirms a plan, not that the meeting happened. An after-event report, gallery, or poll confirms it actually took place.
- A meeting number is only a clue. A confirmed meeting 18 does not guarantee that meeting 19 happened.
- If two sources disagree, write down the disagreement. Do not quietly pick the version that looks nicer.
- Never guess a date, slug, or speaker name. If the source does not say it, the post says “unknown” instead.
- Mark estimated dates explicitly in the data (
date_estimated: true), and only remove the flag once a stronger source confirms it.
These rules made the work slower, but they are the reason I can trust the result today.
I was not the only one doing this
A contributor, Tymoteusz Wojnarowski, used Claude Code independently to recover a large chunk of the earliest history in PR #40 (meetings and talks from 2007 to 2011, built from a speaker’s personal site, old Wayback captures, and GoldenLine), PR #41 (16 meetings from the BlogEngine.NET era), and PR #52 (meetings 9, 11, and 34, plus two posts that got dropped in an earlier merge).
I continued the work myself with agent-assisted pull requests, recovering meetings 54 to 170, the earliest meetings (1 through 11), and the 20-to-32 stretch from the Twitter archive, among others:
- PR #53 - meetings 54 to 170 and ten beach meetups from Meetup
- PR #56 - meetings 20 to 32 from the Twitter archive
- PR #57 through PR #60 - the earliest meetings, 1 through 11
- PR #74 and PR #76 - follow-up detail recovery for the oldest meetings
GitHub’s automated Copilot code review checked many of these pull requests alongside my own, repeatedly catching small but real issues: a misspelled street name, a missing archive link, and a technology name that should have been in bold on first mention.
Where the information came from
The research leaned on a handful of source types, reused across almost every session:
- the Wayback Machine, for snapshots of every past version of the site, including the archived
wrocnet.github.ioindex - the very first site,
wroc.net.isvclub.com, covering meetings 1 through 4 and beyond: the plan for meeting 1, a homepage snapshot confirming meeting 2, the after-event report for meeting 3, and the photo gallery for meeting 4 - the archived Wroc.NET Twitter/X profile, plus an exported HTML copy of the same profile for the years it covers
- Meetup, the group’s current platform and the main source for talks and venues since 2013
- archived GoldenLine registration pages, from when the group used it to sign up attendees
- a speaker’s personal site, gasior.net.pl, which kept its own list of talks with dates
- Crossweb, for one event not archived anywhere else
- old forum threads, photo galleries, and polls hosted on the group’s own past sites
- the project’s pull requests and issues on GitHub, where every recovered fact and open question is documented with its source
What I took away from this
Writing code was the smaller part of this project. Most of the effort went into research: finding sources that disagreed with each other, deciding which one to trust, and writing “we do not know” when that was simply true. The agent could browse the web, fetch pages, and read structured data on its own, but it still needed me to set the rules for what counts as proof.
If you want to see the result, the archive is live at wrocnet.org. The full investigation is public too, pull request by pull request, on GitHub.
Illustrations in this post were generated with GPT.